
Issue with [netsend/receive]?
@jameslo said:
@ddw_music Both--multiple patches in the same Pd instance, or multiple Pd instances on one machine. Not sure why your single process requirement is necessary since some DAWs sandbox plugins. But I'm way out on a limb.
OK, then, this:
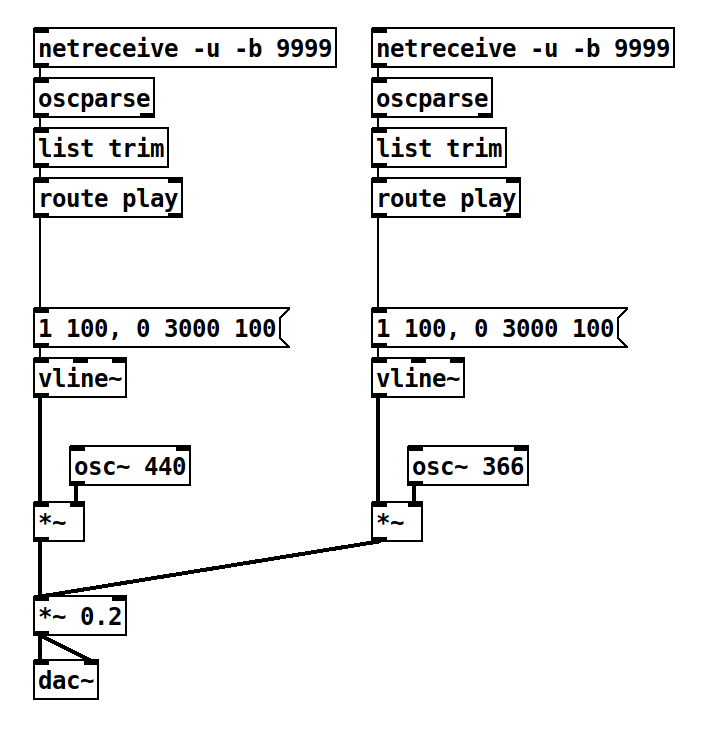
I created the 440 Hz stack first, and the 366 Hz stack second. When I trigger it from SuperCollider like this:
n = NetAddr("127.0.0.1", 9999);
n.sendMsg("/play");
... I get the 366 Hz F#, not the 440 Hz A. I don't have time to split this into two patches and run two instances of Pd at the same time. You're welcome to try. 2-netreceive.pd
At minimum, the silent failure here is a bit troubling: Since it's not valid to have multiple netreceive objects listening to the same port, shouldn't there be a console message, like "port 9999 is already in use")? And since the newer object causes the problem, shouldn't it be the one that doesn't work instead of clobbering any prior netreceives? (FWIW, SC has a different silent failure. Its default UDP receive port is 57120. If that port is busy when an sclang instance starts up, then the second instance will take port 57121 with no warning, so any external software that expects to send OSC to SC on port 57120 will magically not work.)
hjh
 posted in technical issues
Issue with [netsend/receive]?
@ddw_music Why is this a plugdata issue? Does it work in Pd? I'm asking because it would be good to know if plugdata had to rewrite Pd's networking stuff in order to run as a plugin.
 posted in technical issues
Issue with [netsend/receive]?
Maybe you can use one [netreceive] to serve available ports and others in [clone].
- The instance first ask the fixed port for a dynamic port number, then close the connection (and don't take care anymore of its output so if the disconnection is delayed and the server still push something, it's discarded)
- The instance open then another connection with the given dynamic port.
At server side the [netreceive]s get their ports numbers from the $1 which contain the clone instance number. You can start the port minimal number where you want with the -s argument of [clone].
The callback is sent back to the main patch throw the clone instance outlet.
 posted in technical issues
Issue with [netsend/receive]?
I tested with instances running on 2 different machines, and I left the connections open. The "backwards" response to the second instance was also sent to the first instance! So this must be the expected behavior of "backwards", can anyone confirm? i.e. it sends a message back to all connected clients.
I also noticed that [netreceive -f 8000] adds a right-most outlet that lists the originating IP address and port of the incoming connection. It reports the same info as TCPView. If instead of using the "backwards" feature, I try making a netsend connection to the originating IP address and port, the connection is refused. So "backwards" is not the same thing (which is probably obvious to anyone who knows networking).
I see that you can tell the server what port to use for replies if you use UDP, but if the instance could know which ports in a pool of ports were available, then it could derive its own ordinal ID, e.g. if 5 of the ports are already taken, then we must be Number Six (but we would still not know who is Number One).
I added a toggle to show whether [netsend] thinks the connection is open and a numberbox to show how many connections [netreceive] thinks are open, and in the REAPER plugin test, each instance thinks it's open even when nothing is listening on localhost:8000, and there is no error message in any plugdata console. Even weirder, each instance thinks it's closed after the [disconnect( is issued, even though both TCPView and instanceIDService report 6 open connections. Is this a plugdata issue? What other tests would you perform to investigate further? The standalone tests all behave similarly in standalone plugdata.
Finally, I have a theory for why the plugin behavior differs from the standalone behavior. In the latter case, the instances are instantiated so quickly that only the first backward message gets broadcast before all instances disconnect. But REAPER has a lot more work to do, initializing each track, loading plugdata and then restoring plugdata to its saved state, so there's more time between instantiations. The fact that the connections aren't being closed explains why the first instance sees all 6 replies, the second sees the last five, ..., and the last only sees the last reply. So if I make each instance ignore all but the first reply, I get the result I wanted! But in my working life as a programmer, I and my colleagues would've pejoratively called that a hack because it depends on REAPER's timing, which is unspecified, so I'm not really celebrating. For instance, if I run the instanceIDService as the first VST plugin, things are broken.
I'm also going to go out on a limb and say that I think [netreceive] is under-featured. In a Python example I found, they create a socket, bind it to a port, and start it listening. When a client connects, the socket returns a connection from/to which you get/put data. [netreceive] seems to be acting as both the socket as well as the aggregate of all the connections. That's not right! (Or is it?)
test instance ID.zip
posted in technical issues
On-air light, trouble receiving int via OSC
@jbaker said:
I think you're right about the python script... I've finally looked.
It looks like it's sending OSC to 10023, and...it kind of looks like it's receiving on port 1024..? I'll try a [netreceive 1024] object and see what happens.
Python docs say that the number given to recv is the size of the receive buffer, not the port.
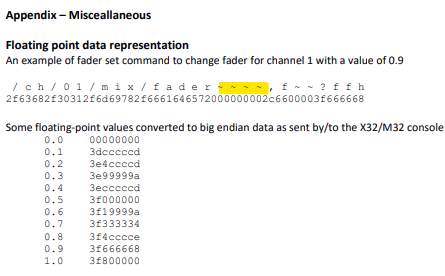
The snippet from the X32 docs that you posted is unambiguous: replies are sent back to the requester's IP and port. So the netsend right-outlet approach should be correct.
Everybody gets their head tied in knots over send/receive ports.
When you connect a netsend, this is giving the IP and port TO which messages will be sent: TO port 10023. The message packet itself contains the sender's IP and port. In Pd, the FROM port is chosen randomly and AFAIK there is no way to know it -- so there's no way to open a netreceive on Pd's sending port. So let's say Pd chose port 45227. You send a message to the X32 and the packet includes your computer's IP and port 45227. The X32 (per documentation that you showed) should send its reply to the computer's IP and port 45227, where it would come out the netsend's right outlet.
I'm still suspecting firewall here. You said it's working on the Pi -- if the Pi isn't running a firewall but your computer is, that could block incoming messages.
"Suspecting" may be too strong -- at least, it's necessary to rule that out. (One not-so-ideal thing about Pd's use of random port numbers is that, in this case, you'd have to open a wide range of ports, or disable the firewall. If you could specify Pd's sending port, then you could open only that port in the firewall... but you don't know which one to open, so you'd have to open thousands of them.)
just the [netsend] on the left of the screenshot below........ it must be told to use the same port for send and receive...... so [connect port sameport(
That doesn't sound quite right to me. Pd here should send to 10023, but it will be sending from a port of its choosing, which isn't 10023. The X32 is sending back to the originating port (not to its own receiving port). So I think "connect aaa.bb.cc.ddd 10023 10023" would not work. The replies from the X32 will not be going to port 10023 on the computer.
hjh
posted in technical issues
On-air light, trouble receiving int via OSC
@ddw_music Thanks for your reply!
About the two possibilities:
-
No configurable port for receiving or sending
-
Yes- I agree! That wouldn't make sense for the X32 to reply on a random UDP port.
I think you're right about the python script... I've finally looked.
It looks like it's sending OSC to 10023, and...it kind of looks like it's receiving on port 1024..? I'll try a [netreceive 1024] object and see what happens.
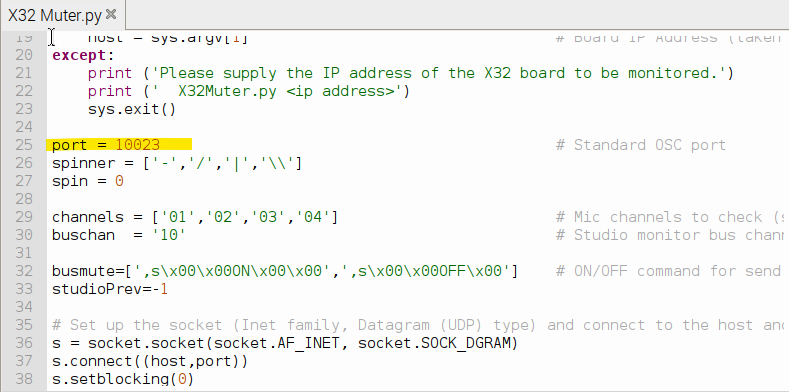
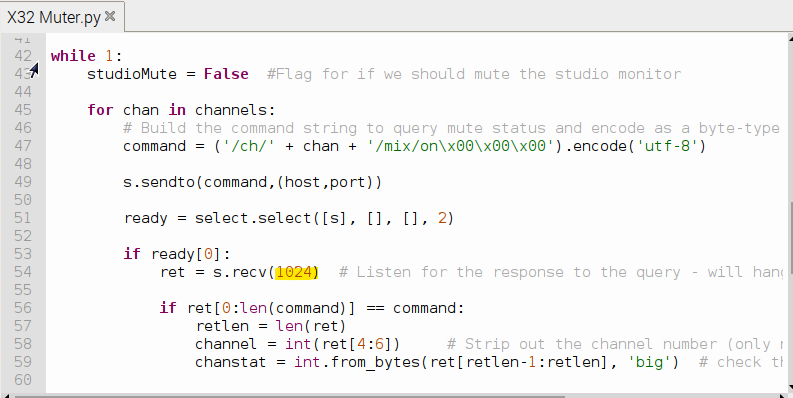
@ddw_music: "One other thing to check -- are you 100% certain that the Pd machine's firewall is not blocking high port numbers?"
I'm not 100% certain. Yes, the LiveToolKit x32 software is running on the Pi and can read the OSC messages from the X32... But if Pd chooses randomly the receive port with [netsend]... Should I just use a [netreceive (port#)] object? But I see what you're saying about the firewall. I'll try SuperCollider (thank you, more tools are always nice) and see what happens... Thanks for including that screenshot of SC to get me started!
Tilda's: Fair enough! I got the idea in my head from the X32 OSC documentation.
Will reply here with what I find... Thank you both very much! 
 posted in technical issues
netsend not receiving or outputting UDP responses
@chvolow24 said:
@ddw_music said:
Lack of handshaking means (AFAIK) UDP doesn't have a concept of sending back to the originating location.
This actually isn't true. The first two bytes of a UDP datagram specify the source port, and the encapsulating IP packet includes the source address.
Yes (and this info is available e.g. in SuperCollider, where every received message is accompanied by an address object indicating the source).
It is still profoundly weird to me that one would send a return message by passing a list to netreceive, and receive it in netsend. There may be some reason in TCP why that's necessary, but wouldn't surprise me if such an inversion were unnecessary in UDP. I would just use netreceive for receiving and netsend for sending, and be done with it.
hjh
posted in technical issues
netsend not receiving or outputting UDP responses
@chvolow24 said:
What would prevent the responses from being received, output, or printed by
netsend?
UDP is a dumb protocol: no handshaking, no confirmation of message receipt -- it's "I sent it out the port, then we just hope for the best."
Lack of handshaking means (AFAIK) UDP doesn't have a concept of sending back to the originating location. Because it's dumb, it's simpler: [netsend -u] only sends, [netreceive -u] only receives. The idea of passing a message into [netreceive] and it being sent somewhere doesn't make sense in UDP land.
In the helpfile, the "send back" functionality is demonstrated for TCP connections but not for UDP. I don't think this is a casual omission -- I think this actually reflects the functionality.
hjh
posted in technical issues
netreceive FUDI parsing
I should add that using fudiparse works fine:
[netreceive -u -b 5400]
|
[fudiparse]
|
[unpack %f %f]
My expectation was that the above patch was equivalent to this:
[netreceive -u 5400]
|
[unpack %f %f]
But the latter does not work now.
 posted in technical issues
Controlling PD over internet
@rph-r You can use [netreceive] in the installation patch.
Then use [netsend] in your remote patch.
Once your remote patch is connected you will be able to receive messages back from the installation through those same objects (see the help files).
If you use a tcp connection in [netsend] and [netreceive] then the left outlet of [netsend] indicates whether it connected (the value will change from one to zero when you try to send a message if the connection has been lost).
That is because the TCP protocol needs an acknowledgement packet sent back, or it will send the packet again..... and again until it times out. UDP will not do that.
If you need an "alarm" that the connection has been lost, or that the installation patch has stopped sending messages, then add a [metro] sending a ping back to [netsend] from the [netreceive] in your installation patch.
Then you could set up an auto reconnect in your remote patch.
You can only "find" another computer on the net if its IP has changed by using DNS lookup, and if an address changes it can take up to 2 days for all the worlds DNS servers to be updated.
Maybe something like DynDns is quicker, but if you are instigating the connection using your controller (remote) computer then you don't need that anyway.
You will always be able to reach the installation computer from any internet address.
David.
P.S. of course you can set up and test on your local network before implementation.
 posted in technical issues